- How To Disallow Specific Pages In Robots.txt
- How To Disallow Access To Specific Folders
- How To Disallow All (Block Your Whole Site) In Robots.txt
- How To Allow Access To All Crawlers And Content
- How To Use Allow And Disallow Together
- How To Use Wildcards (* and $) In Robots.txt
- How To Disallow Specific Bots
- How To Disallow All Bots Except Google
- How To Prevent Crawling of URL Parameters
- How To Restrict Image Indexing
- How To Block AI Crawlers From Accessing Your Content
- How To Prevent Content From Appearing In Search Results Using NoIndex Tag
- What "Blocked By Robots.txt" Means In Search Console (And How To Remove It)
- How To Manually Overwrite The robots.txt File In WordPress
- Robots.txt Rules To Remember
- Learn More About Robots.txt And SEO
Robots.txt is a file located in your website's root folder. It lets you control which pages or parts of your website search engines can crawl.
When search engine bots visit your website, they check the contents of robots.txt to see if they can crawl the site and which pages or folders to avoid. The main command in the file is Disallow, which tells crawlers not to visit a URL path. Its opposite, Allow, opens up a path inside a blocked area.
One thing to understand before you start: robots.txt controls crawling, not indexing. Google's own documentation says it is not a mechanism for keeping a page out of Google. A disallowed page can still appear in search results, without a description, if other pages link to it. To keep a page out of the results, use the noindex tag instead.
How To Disallow Specific Pages In Robots.txt
To prevent search engines from crawling specific pages, you can use the disallow command in robots.txt.
For example, if you want to stop search engines from crawling a "thank you" page that users land on after submitting a form, you would add the following lines to your robots.txt file:
User-agent: *
Disallow: /thank-you.html
This tells all search engines (using User-agent: *) not to crawl the "/thank-you.html" page.
Ensure the path you enter matches the exact URL structure of the page you want to disallow. Paths are case-sensitive, so "/Thank-You.html" and "/thank-you.html" are two different rules.
If the URL of your "thank you" page is https://www.example.com/thank-you.html, you should only enter "/thank-you.html".
If the URL of your "thank you" page is https://www.example.com/checkout/thank-you.html, you should enter "/checkout/thank-you.html" in your robots.txt.
You can also disallow multiple pages by adding one Disallow line per path:
User-agent: *
Disallow: /thank-you.html
Disallow: /some-other-page
And even pages that have a specific extension. For example, to block all .html pages use:
User-agent: *
Disallow: /*.html$
You can also disallow specific bots only from accessing a page. For example, to block Google from crawling a page but allow all others, you can use this:
User-agent: Googlebot
Disallow: /thank-you.html
This tells Google's bot (Googlebot) not to crawl the "thank-you.html" page while allowing other search engines, like Bing, to access it.
How To Disallow Access To Specific Folders
To disallow access to specific folders on your website, you can specify those folders in your robots.txt file using the Disallow command. This stops search engines from crawling any content within those directories.
For example, if you want to block search engines from accessing a folder called "private" and another folder named "tmp", your robots.txt file would look like this:
User-agent: *
Disallow: /private/
Disallow: /tmp/
In this example, the trailing slash after the folder name (/private/ and /tmp/) indicates that everything within those folders should not be crawled.
The trailing slash matters. "Disallow: /private" without it also blocks "/private-offers.html" and any other URL that starts with "/private", because a Disallow rule matches the beginning of the URL path.
How To Disallow All (Block Your Whole Site) In Robots.txt
To block your whole site in robots.txt, you can prevent all search engines from crawling any part of your website using the "Disallow: /" command. The single forward slash means the root folder, so the rule covers every URL on the site.
This is also referred to as the "disallow all" command.
User-agent: *
Disallow: /
This stops search engines from crawling your site, but it does not guarantee that your pages will disappear from search results. URLs that other sites link to can still be indexed and shown without a description.
Common reasons to use it include:
- Websites that are still under development, and you don't want search engines to crawl them yet.
- Testing or staging environments.
For a staging site, "disallow all" is not enough on its own. Password-protect it, or add a noindex tag to every page, if it must stay out of search results completely.
How To Allow Access To All Crawlers And Content
To unblock your website and give access to all crawlers to all your website content, leave the disallow command empty as shown below.
This is also known as "allow all".
User-agent: *
Disallow:
When the Disallow: line is left empty, it tells all search engine bots that they are free to crawl every page on your site. This is the default behavior if search engines cannot locate a robots.txt file in your website's root folder.
"Allow: /" does the same job. Both versions are valid, so use whichever you find easier to read.
How To Use Allow And Disallow Together
The Allow command lets crawlers access a path that a broader Disallow rule would otherwise block. It is useful when you want to block a folder but keep one file or subfolder inside it open.
The default robots.txt file that WordPress generates is a good example:
User-agent: *
Disallow: /wp-admin/
Allow: /wp-admin/admin-ajax.php
This blocks the WordPress admin folder but lets crawlers reach admin-ajax.php, which some themes and plugins use to load content on public pages.
When an Allow and a Disallow rule both match the same URL, Google follows the most specific rule, meaning the one with the longer path. In the example above, "/wp-admin/admin-ajax.php" is longer than "/wp-admin/", so the Allow rule wins for that file.
If two matching rules are the same length, Google uses the least restrictive one, which is the Allow rule. The order of the lines in the file makes no difference.
How To Use Wildcards (* and $) In Robots.txt
Google and Bing support two special characters in Allow and Disallow paths:
- * matches any sequence of characters, including none.
- $ marks the end of the URL.
Some examples:
User-agent: *
# Block every URL that contains a question mark
Disallow: /*?

# Block every PDF file
Disallow: /*.pdf$

# Block "print" subfolders inside any folder
Disallow: /*/print/
Without the "$", "Disallow: /*.pdf" would also block a URL like "/guide.pdf-download/". With it, only URLs that end in ".pdf" are blocked.
Lines that start with "#" are comments. Crawlers ignore them, so you can use them to explain each rule to whoever edits the file next.
How To Disallow Specific Bots
To disallow specific bots from crawling your site, you can target them individually in your robots.txt file by specifying their user agents. This allows you to block access to your site for certain bots while still allowing others to crawl it.
For example, if you want to block "Bingbot" but allow all other bots, your robots.txt file would look like this:
User-agent: Bingbot
Disallow: /

User-agent: *
Disallow:
In this example above, Bingbot is blocked from accessing any part of your site, as indicated by Disallow: /.
The User-agent: * followed by an empty Disallow: line allows all other bots to crawl your entire site.
A crawler follows only the group that names it most specifically. Bingbot obeys its own group and ignores the "User-agent: *" group, while every other bot follows the "*" group.
When blocking specific bots, ensure that the bot name specified in User-Agent is correct. Google treats the user agent name as case-insensitive, but a misspelled name matches nothing. You can find a list of all known bots here.
How To Disallow All Bots Except Google
To let Google crawl your site while blocking every other crawler, give Googlebot its own group with an empty Disallow line, and block everyone else:
User-agent: Googlebot
Disallow:

User-agent: *
Disallow: /
Googlebot matches its own group and crawls everything. All other bots fall into the "*" group and are blocked.
You can add more groups in the same way. For example, add "User-agent: Bingbot" with an empty Disallow line to let Bing crawl as well.
Keep in mind that robots.txt is a request, not an enforcement. Reputable search engines follow it, but bad bots can ignore it completely.
How To Prevent Crawling of URL Parameters
If your site uses URL parameters (like ?id=123 or ?sort=asc), search engines might crawl many versions of the same page. To prevent this, you can block search engines from crawling URLs with specific parameters:
User-agent: *
Disallow: /*?id=
Disallow: /*&id=
The first rule blocks any URL where "id" is the first parameter (?id=). The second catches it when it comes later in the query string (&id=).
This helps you optimize your crawl budget, so crawlers spend their time on the pages that matter. It does not remove parameter URLs that are already indexed. Use canonical tags for duplicate versions of a page that you want Google to consolidate.
How To Restrict Image Indexing
If you want to prevent images on your site from appearing in Google Image Search, you can block image files from being crawled. This is one case where robots.txt does keep files out of Google: Google's documentation lists image, video and audio files as content that robots.txt can keep out of search results.
Assuming your images are in the "/images/" folder residing in your website's root directory, you can use the following command:
User-agent: Googlebot-Image
Disallow: /images/
Blocking Googlebot-Image also removes those images from Discover and from other Google Search features that show images.
How To Block AI Crawlers From Accessing Your Content
With the rise of AI tools such as ChatGPT, Claude, and Gemini, you might want to control how their bots use your site. AI companies run separate crawlers for separate jobs, so decide first what you want to block:
- Training crawlers collect content to train AI models.
- Search crawlers decide whether your pages can be shown and cited in AI search answers.
- User agents fetch a page when a person asks the assistant to visit it.
These are the main ones:
| User agent | Company | What blocking it does |
|---|---|---|
| GPTBot | OpenAI | Stops your content from being used to train OpenAI's models |
| OAI-SearchBot | OpenAI | Stops your pages from being shown in ChatGPT search answers |
| ClaudeBot | Anthropic | Stops your content from being collected for training Anthropic's models |
| Claude-SearchBot | Anthropic | Stops it from crawling your pages to improve Claude's search results |
| Google-Extended | Stops your content from being used to train Gemini models and for grounding in Gemini apps. It does not affect Google Search |
For example, to keep your content out of OpenAI's model training while still appearing in ChatGPT search, you would add the following lines:
User-agent: GPTBot
Disallow: /

User-agent: OAI-SearchBot
Allow: /
Blocking a search crawler such as OAI-SearchBot means your pages can no longer be cited in that assistant's answers, so think twice before blocking it if you want traffic from AI search.
Google-Extended is a control token, not a separate crawler. Google says it does not affect your site's inclusion in Google Search or act as a ranking signal.
For a complete list of AI bots, visit this page.
How To Prevent Content From Appearing In Search Results Using NoIndex Tag
As mentioned above, adding directives in robots.txt cannot guarantee that a page will not show up in the search results. A disallowed page is not crawled, but if other pages link to it, Google can still index its URL and show it in search results without a description.
To keep content out of the search results, you must use the noindex tag.
When you use the noindex tag, you tell search engines that you don't want a specific page included in their index. Thus, it won't appear in search results or count as content when evaluating your website's authority.
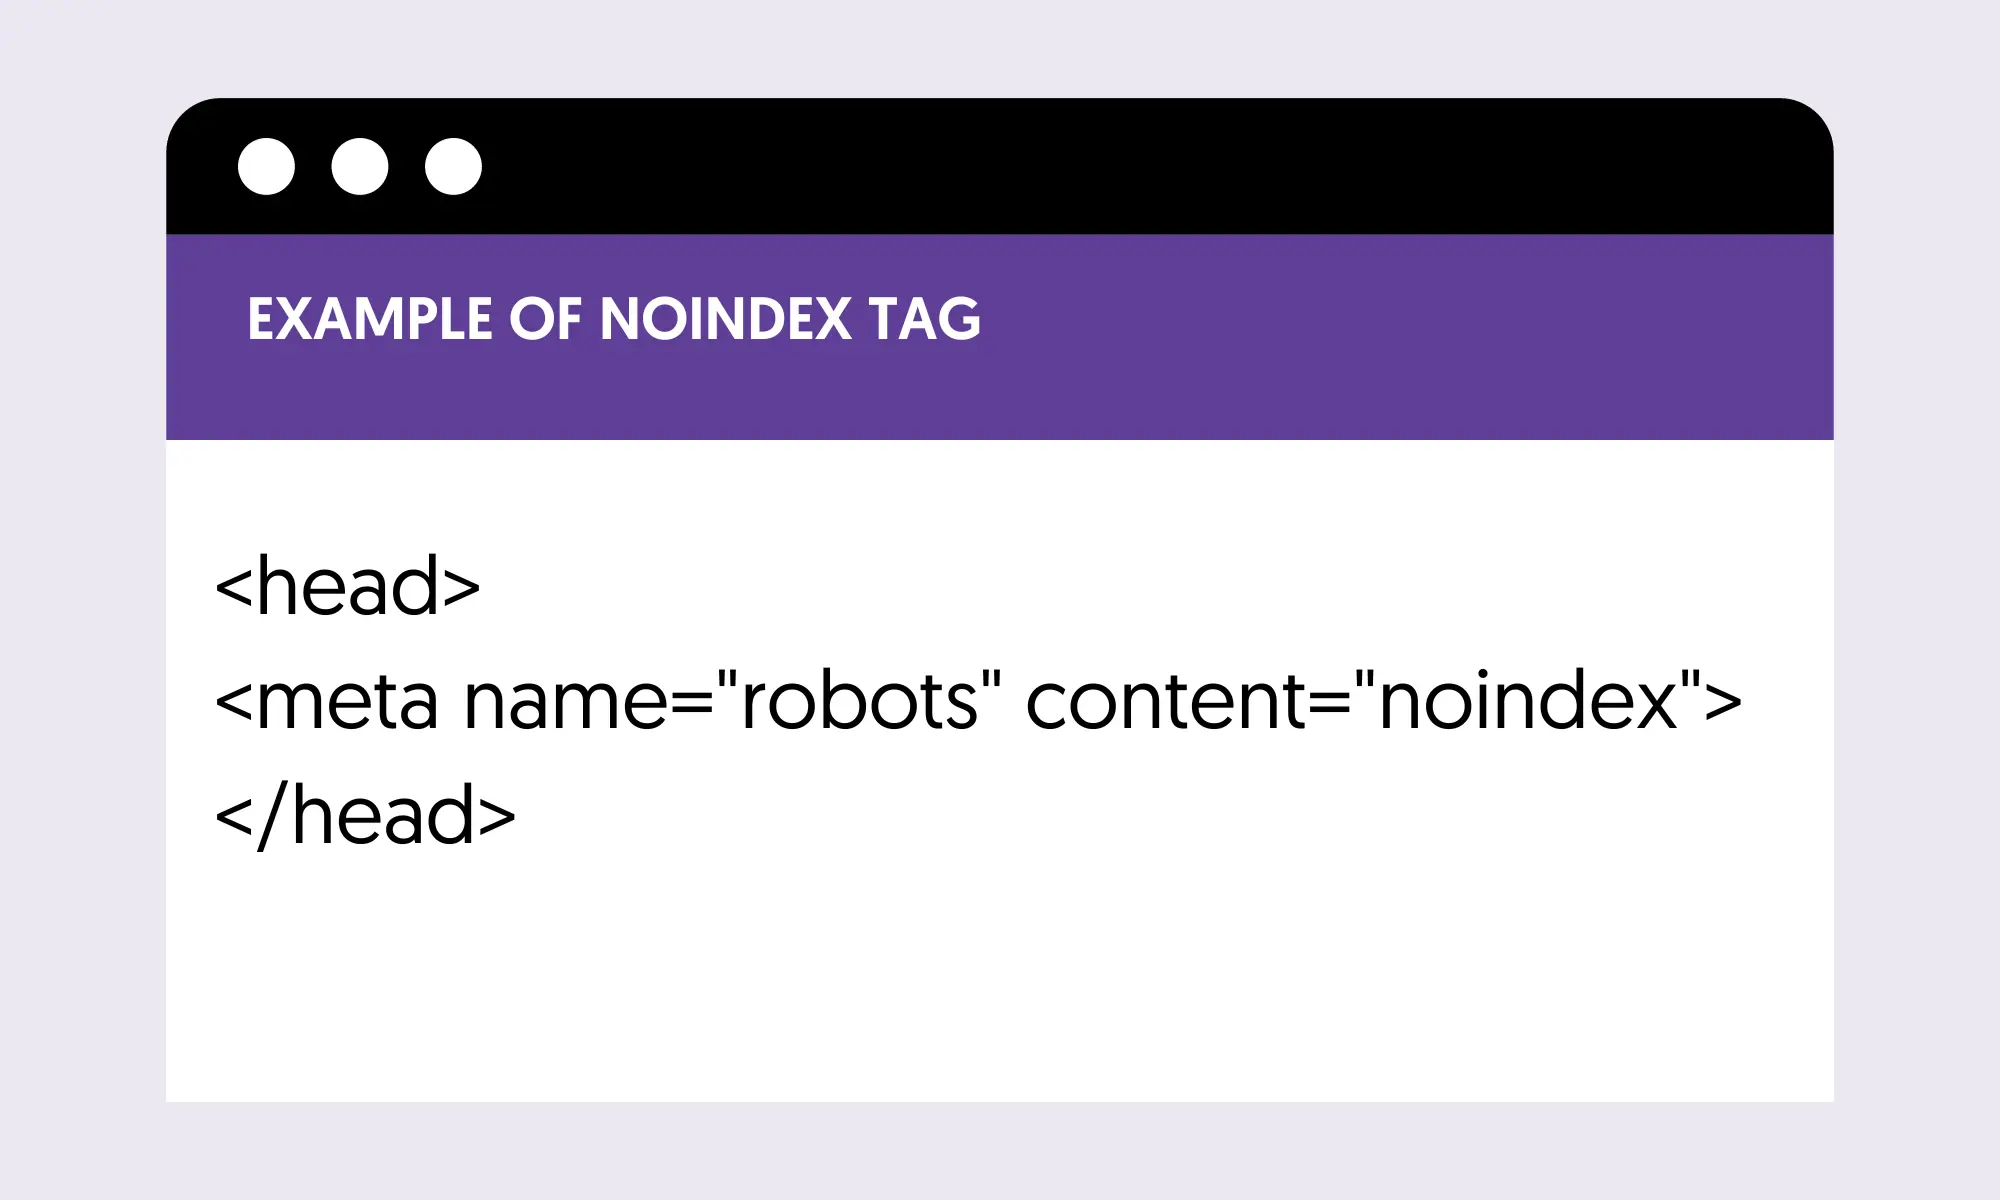
The noindex tag is placed in the HTML of the page within the <HEAD> section, like the example below.
Make sure not to block a page in robots.txt if you've added a "noindex" tag, as search engines need to crawl the page to see and process the tag.
Adding "noindex" as a line in robots.txt does not work. Google does not support it there, and the same goes for "crawl-delay".
What "Blocked By Robots.txt" Means In Search Console (And How To Remove It)
The Page indexing report in Google Search Console shows two statuses related to robots.txt:
- Blocked by robots.txt - Google found the URL but did not crawl it because a rule in your robots.txt blocks it. The page is not indexed.
- Indexed, though blocked by robots.txt - Google indexed the URL without crawling it, usually because other pages link to it.
If the blocked pages are ones you don't want in Google, you can leave the first status alone. For the second, remove the Disallow rule and add a noindex tag, so Google can crawl the page and see that it should drop it.
If you blocked a page by mistake, follow these steps to remove the block:
- Find the rule - Open https://yourdomain.com/robots.txt and look for the Disallow line that matches the URL. Remember that a rule blocks every URL that starts with its path.
- Edit or delete the rule - Update the file on your server, or in your SEO plugin if you use WordPress.
- Ask Google to fetch the new file - Google caches robots.txt for up to 24 hours. To speed things up, open the robots.txt report in Search Console (under SETTINGS) and request a recrawl.
- Request indexing - Use the URL Inspection tool on the affected pages and click "Request indexing".
How To Manually Overwrite The robots.txt File In WordPress
WordPress, by default, uses a virtual robots.txt file that is generated dynamically based on your WordPress settings and plugins. Since it's a virtual file, you cannot access its contents through a file manager.
The easiest way to edit it is through your SEO plugin. In Yoast SEO, go to Yoast SEO > Tools > File editor. In Rank Math, go to Rank Math SEO > General Settings > Edit robots.txt.
If you don't use an SEO plugin, or you want full control over the file, you can replace the virtual file by uploading your own robots.txt file to your website's root folder.
Follow these steps:
- Access your site via FTP or File Manager - Use an FTP client like FileZilla or the File Manager tool in your hosting control panel (e.g., cPanel) to access your website's files.
- Navigate to the root directory - This is usually named public_html, www, or it might simply be the main directory of your domain. This is where the robots.txt file should reside.
- Create a file named robots.txt - Use a text editor like Notepad to create the file and enter your desired rules. The file name must be all lowercase.
- Upload and verify your file - Save your changes and upload the robots.txt file to your site's root directory via FTP or File Manager. After uploading, check that the file is accessible by visiting https://yourdomain.com/robots.txt in your browser.
- Submit robots.txt to search engines - You actually don't have to submit your robots.txt to search engines. They will discover it automatically. Wait a few days and then check the robots.txt report in your Google Search Console. You can find the report under SETTINGS.
Once a physical robots.txt file exists in your root folder, it replaces the virtual one, and some SEO plugins will no longer let you edit it from the dashboard.
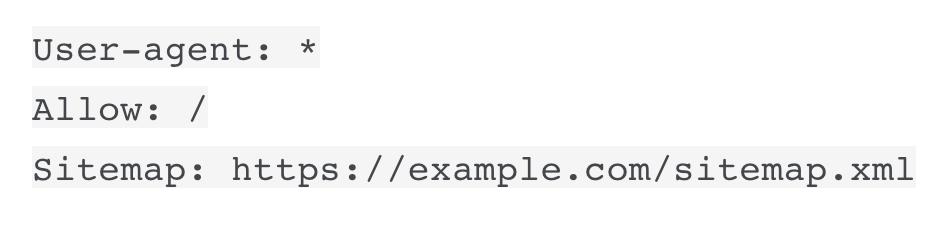
A good example of a robots.txt for most WordPress websites is:
User-agent: *
Allow: /
Sitemap: https://example.com/sitemap.xml
It allows crawlers to access all content and also specifies the location of the XML sitemap file. The Sitemap line must use the full URL, including https://.
Robots.txt Rules To Remember
- Crawling, not indexing - Disallow stops crawling. Use noindex or password protection to keep a page out of search results.
- Paths are case-sensitive - "/Private/" and "/private/" are different rules. The words "User-agent", "Disallow" and "Allow" are not case-sensitive.
- One file per host, in the root - Crawlers only read https://yourdomain.com/robots.txt. A robots.txt file in a subfolder is ignored, and a subdomain needs its own file.
- It is public - Anyone can read your robots.txt, so don't use it to hide sensitive pages. Listing a private folder there tells people where to look.
- It is not a security tool - Following robots.txt is voluntary. Search engines respect it, but scrapers and malicious bots can ignore it.
- Size limit - Google reads the first 500 KiB of the file and ignores the rest.
- Changes are not instant - Google generally caches robots.txt for up to 24 hours.
Learn More About Robots.txt And SEO
Use the following guides and resources to learn more about Robots.txt and SEO.
- Technical SEO Best Practices
- Best Technical SEO Courses (include lessons on Robots.txt)
- Introduction to Robots.txt (Google Guidelines)
- How Google Interprets the robots.txt Specification (Google Guidelines)